The real problem with robots.txt is not whether it exists. The real problem is using it without understanding what it controls. A small file can protect crawl budget, but it can also hide valuable pages from search engines if it is configured badly.
For business owners, this is not a technical detail. If important pages are blocked, Google may crawl less efficiently, index fewer pages, and miss content that supports visibility, credibility, and qualified leads.
Direct answer: what does robots.txt actually do?
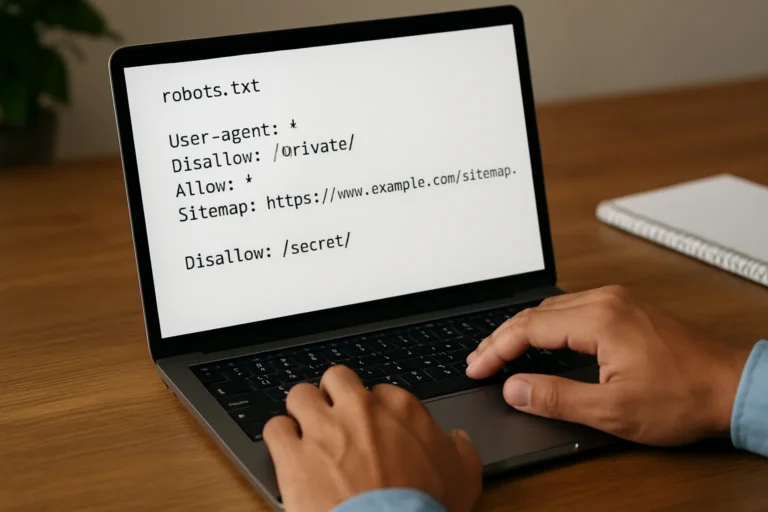
robots.txt tells search engine crawlers which parts of a website they are allowed to request. It is useful for controlling exploration, reducing unnecessary crawling, and keeping bots away from low-value areas such as admin folders or internal search pages.
It does not guarantee privacy, and it does not remove pages from Google by itself. If a page is already known and linked elsewhere, it may still appear in search results even if crawling is restricted. That is why robots.txt must be used with a clear SEO strategy, not as a shortcut.
Table of contents
Why does robots.txt matter for SEO and business performance?
A website must do more than exist. It must be found, understood and crawled efficiently. robots.txt helps search engines spend time on the pages that matter most instead of wasting resources on low-value URLs.
This matters especially for larger websites, ecommerce stores, service websites with many landing pages, and platforms that generate duplicate or parameter-based URLs. A clean crawl path helps search engines discover the right content faster.
For companies working on construction company website development, recruitment agency website development or psychologist website development tunisia, this becomes important very quickly because service pages, location pages and conversion pages must remain accessible.
What should you block in robots.txt, and what should stay accessible?
The goal is not to block as much as possible. The goal is to block the right things and leave important pages open.
| Area | Typical action | Business impact |
|---|---|---|
| Admin folders | Block | Reduces wasted crawling on non-commercial pages |
| Internal search results | Block | Avoids thin or duplicate pages in crawl paths |
| Staging environments | Block | Prevents unfinished pages from being explored |
| Core service pages | Keep open | Protects visibility and lead generation |
| Blog articles | Keep open | Supports authority, traffic and topical relevance |
| Product or category pages | Keep open | Supports commercial search intent and conversions |
If your website includes content such as learning platform website development or daycare kindergarten website development, the main landing pages should remain crawlable because they often target high-intent searches and local visibility.
What are the most common robots.txt mistakes?
Most problems come from overblocking. A single wrong line can stop crawlers from reaching pages that generate traffic or leads.
Blocking the wrong folders
Many teams block entire directories because they look unimportant, but those directories may contain CSS, JavaScript or images needed for rendering. If Google cannot render the page properly, it may evaluate the page with less confidence.
Using robots.txt to hide sensitive content
robots.txt is not a security tool. If a page must stay private, it should be protected with authentication or server-level restrictions. Blocking it in robots.txt alone is not enough.
Blocking pages that should be indexed
This is the most expensive mistake from a business point of view. If a service page, category page or article is blocked, it may lose the chance to rank, which means fewer qualified leads and weaker commercial performance.
Forgetting that crawl control is not index control
Some pages can still appear in search results even if they are blocked from crawling. If the objective is removal from indexing, a different technical approach is needed.
How should a business configure robots.txt correctly?
Step 1: Map the website structure
Start by identifying the pages that drive revenue, brand trust and organic traffic. These pages must remain accessible to crawlers.
Step 2: Identify low-value or technical areas
Look for admin sections, duplicate parameter URLs, internal search pages and temporary environments. These are the usual candidates for blocking.
Step 3: Check what search engines already crawl
Use crawl data and search console reports to understand where bots spend time. The objective is to reduce waste without creating accidental barriers.
Step 4: Test before publishing
A robots.txt file should be tested carefully before deployment. A small syntax error can affect the entire site. This is especially important after a redesign, migration or platform change.
Step 5: Review after major changes
When a site adds new sections, new filters or new markets, the crawl rules should be reviewed again. SEO should not be added after the website is finished. It should be planned from the beginning.
How does robots.txt support SEO, AEO and GEO?
robots.txt supports SEO by helping search engines focus on the pages that matter most. It supports AEO by making it easier for crawlers to reach clear, answer-oriented content. It supports GEO because AI search systems and answer engines rely on structured, accessible content sources.
For AI-driven discovery, clarity matters. If important pages are blocked, the system has less content to understand, cite or summarize. That can reduce visibility in both classic search and AI-assisted search experiences.
At THE ROAD, the objective is not only to create a site visually clean. The objective is to build a digital presence that is fast, credible and technically readable so it can support growth over time.
What is the business impact of a bad robots.txt file?
A slow website does not only create a technical problem. A badly controlled crawl path creates a business problem, because search engines may spend less time on important pages and potential clients may not find the content that should bring them in.
| Robots.txt decision | Technical effect | Business result |
|---|---|---|
| Block low-value URLs | Cleaner crawl path | Better use of crawl budget |
| Leave key pages open | Easy discovery and rendering | Stronger visibility and indexing |
| Block important pages by mistake | Reduced crawling | Traffic loss and fewer leads |
| Review after redesign | Prevents technical regressions | Protects rankings and trust |
For businesses competing on local visibility, service quality and trust, this file is small but strategic. It helps protect the pages that support customer acquisition.
When should you ask an agency to review robots.txt?
You should review robots.txt before a website launch, during a redesign, after a migration, and whenever organic traffic drops without an obvious reason. These are the moments when crawl issues often appear.
If your website has many service pages, location pages or content sections, a professional review can prevent expensive mistakes. This is especially relevant for companies that depend on organic search to generate qualified leads.
Chez THE ROAD, l’objectif n’est pas seulement de créer un site web visuellement propre. L’objectif est de construire une présence digitale claire, rapide, crédible et capable de soutenir la croissance de l’entreprise.
FAQ
Does robots.txt hide a page from Google?
No. It mainly controls crawling, not guaranteed removal from indexing. A page may still appear in search results if Google already knows it from links or other signals.
Should I block all duplicate pages in robots.txt?
Not always. Some duplicate pages should be handled with canonical tags, noindex rules or site architecture changes. The right fix depends on the page type and business goal.
Can robots.txt damage SEO?
Yes, if it blocks important pages or resources needed for rendering. A bad configuration can reduce visibility, weaken indexing and limit traffic growth.
Is robots.txt enough to protect private content?
No. It is not a security measure. Private content should be protected with proper access control, not only with crawl restrictions.
How often should robots.txt be checked?
At minimum after a redesign, migration, CMS change or major content update. For larger websites, regular technical SEO audits are the safer approach.
Need a technical review before you lose visibility?
robots.txt is a small file with a big impact. Used well, it helps search engines focus on the pages that support visibility and conversion. Used badly, it can quietly block growth.
If you have a site launch, a redesign or a traffic issue to investigate, THE ROAD can help you review the technical foundation and make sure the right pages stay visible.
You have a web project, a redesign or an SEO need? THE ROAD can support you with a clear, professional and results-oriented approach.